GPU monitoring: the box behind these numbers.
Unless a caption says otherwise, the readings on this page come from one workstation: four RTX A4000s, with a single model loaded across all of them, busy with our own test traffic. These are the numbers the console showed while we recorded figs. 1 and 5. The fit tests further down also used a Quadro RTX 5000, and say so.
- GPUs
- 4 × NVIDIA RTX A4000, 16 GiB each (Ampere, compute 8.6)
- VRAM in use
- 59.4 of 64.0 GiB, one model across all four cards
- PCIe
- Gen 4 x16 per card
- Driver
610.57.04, CUDA 13.3
| Reading | At capture | 24 h busy median | 24 h peak |
|---|---|---|---|
| GPU utilisation, busiest card (%) | 100 | 100 | 100 |
| GPU power, four cards summed (W) | 548 | 530 | 559 |
| Tokens per minute | not shown | 190k | 880k |
Your numbers will be different. That is the point of measuring them.
A number it can’t measure reads “not reported”.
Most GPU dashboards average four cards into one line and draw a missing value as 0. This one gives each card its own panel: temperature against the throttle point its driver reports, power against the card’s own cap, clocks, fan, the PCIe link as it is negotiated right now, and ECC and NVLink when the card has them. Two cards bought eighteen months apart stay two cards, and a value the driver doesn’t give is labelled as missing instead of drawn as zero.
 Throttle point from the driver, not a guess
Why the clock is down, as the driver reports it
Power against its own 140 W cap
NVLink and ECC, as the card reports them
| Per card | Temperature and throttle point, power and its cap, core and memory clocks, fan, PCIe generation and width, ECC, NVLink, and the engine process using the card |
|---|---|
| Per host | VRAM in use, GPU utilisation (the busiest card), power (the sum of the cards) and tokens per minute |
| Per request | Time to first token, inter-token latency and duration, measured at the proxy the same way for both engines |
What each request is waiting for.
The Stats page lists every request in flight with the client’s session and where the request is in its life: queued at the warden, prefill (the engine reading the prompt), thinking, writing a tool call, or answering. A badge gives the share of the prompt likely to be in the replica’s cache. A prefill that runs longer than this box’s learned prefill rate predicts says why it probably waits: behind other prompts on the same replica, a cache that was probably evicted, or slow for no reason the warden can see. The session comes from the id each tool already sends: Claude Code, Codex, OpenCode and pi out of the box, Hermes and Aider with one line of setup.
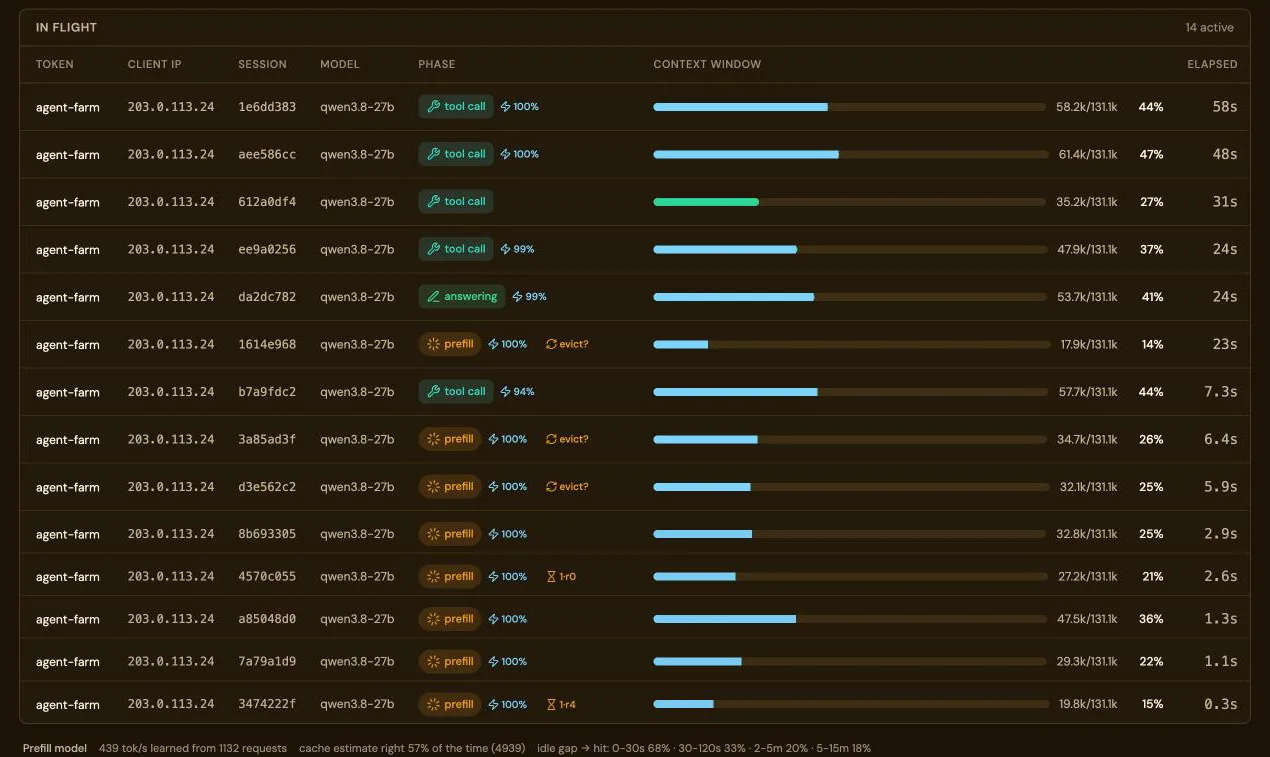 No token yet, cache probably evicted
One prompt ahead of it on replica 4