LM Warden

The next turn lands where the last one left its cache.

An agent resends its whole history every turn, so a long conversation is mostly a prefix the engine has already read. vLLM keeps that work in its prefix cache (the attention state of prompts it has seen) and skips it the next time the same prefix arrives, but only on the replica that did the work: each full copy of the model has its own cache. vLLM’s own balancer sends each turn to whichever replica has the shortest queue, which usually has never seen the conversation, so it reads the whole history again. LM Warden places each new conversation on the least-loaded replica (requests in flight, how full its cache is, and how many live conversations it holds) and keeps it there, using the session id Claude Code already sends. It moves a request only when that replica has 8 requests in flight (the spill threshold).

Why affinity: one conversation over four turnsTwo panels of four replicas. First: each of four turns of one conversation lands on a different replica and is almost entirely prefilled from scratch. Second: all four turns stay on one replica and only the new turn is prefilled; the rest is served from the prefix cache.served from the prefix cacheprefilled from scratchvLLM’s balancer: a turn lands anywherereplica 0replica 1replica 2replica 3t1t2t3t4prefilled again: about the whole history, every turnLM Warden: a conversation stays on its replicareplica 0replica 1replica 2replica 3t1t2t3t4prefilled again: only the new turn
Why affinity: one conversation over four turnsTwo panels of four replicas. First: each of four turns of one conversation lands on a different replica and is almost entirely prefilled from scratch. Second: all four turns stay on one replica and only the new turn is prefilled; the rest is served from the prefix cache.served from the prefix cacheprefilled from scratchvLLM’s balancer: a turn lands anywherereplica 0replica 1replica 2replica 3t1t2t3t4prefilled again: about the whole history,every turnLM Warden: a conversation stays on its replicareplica 0replica 1replica 2replica 3t1t2t3t4prefilled again: only the new turn
Fig. 6Four turns of one conversation on a four-replica model. With vLLM’s balancer, each turn is prefilled (its prompt read into the cache) almost from scratch on whichever replica got it. With LM Warden, the conversation stays on replica 2 and only the new turn is prefilled. A drawing of the mechanism, not a measurement.

Measured on the four-card box: with conversations pinned, the share of prompt tokens served from the cache rose from 56 to 86% at 4 concurrent sessions, and the median time to first byte fell from 2.05 to 0.38 s. Output tokens a minute were higher at every step we ran, and the p95 time to first byte (the slowest 5%) was lower at every step. The number of replicas doing work barely moved (2.71 against 2.83 of four at 4 sessions): the gain is reuse of the cache, not more cards working.

The 24 and 32 session steps are a deliberate overload of four small cards, where waits run to tens of seconds with or without affinity. There the trade-off shows: the tail is still shorter with affinity, but the median is longer. The numbers follow.

GPUs
4 × NVIDIA RTX A4000, 16 GiB each
Model
qwen3-4b-dp4 (Qwen/Qwen3-4B-Instruct-2507), bf16
Layout
data_parallel_size 4, tensor_parallel_size 1
vLLM
0.26.0
LM Warden
This release
Captured
4 October 2026, both arms back to back
Load
Synthetic Claude Code-style sessions from our own harness, not Claude Code itself: a shared system prompt of about 3.5k tokens, a first message unique to the session (6k nominal, about 7.2k to 7.5k measured), then five more turns of about 400 new tokens each, at most 256 tokens out per turn. Closed loop: a session starts its next turn when the last one ends. 3 minutes per step.
Time to first byte by concurrent sessionsMedian and 95th-percentile time to first byte on the four-card box at 4 to 32 concurrent sessions, affinity on against vLLM’s balancer, on a log scale from 0.3 to 100 seconds. 4 sessions: median 2.05 s off, 0.38 s on, p95 3.5 s off, 2.84 s on; 8 sessions: median 2.33 s off, 0.48 s on, p95 6.32 s off, 5.03 s on; 16 sessions: median 3.25 s off, 0.85 s on, p95 26.24 s off, 24.88 s on; 24 sessions: median 5.06 s off, 13.14 s on, p95 58.82 s off, 38.34 s on; 32 sessions: median 12.32 s off, 27.66 s on, p95 82.84 s off, 38.92 s on.affinity onvLLM balancerTime to first byte, median0.3131030100seconds, log scale48162432concurrent sessionsvLLM balancer, 4 sessions: 2.05 svLLM balancer, 8 sessions: 2.33 svLLM balancer, 16 sessions: 3.25 svLLM balancer, 24 sessions: 5.06 svLLM balancer, 32 sessions: 12.32 svLLM balanceraffinity on, 4 sessions: 0.38 saffinity on, 8 sessions: 0.48 saffinity on, 16 sessions: 0.85 saffinity on, 24 sessions: 13.14 saffinity on, 32 sessions: 27.66 saffinity onTime to first byte, p950.3131030100seconds, log scale48162432concurrent sessionsvLLM balancer, 4 sessions: 3.5 svLLM balancer, 8 sessions: 6.32 svLLM balancer, 16 sessions: 26.24 svLLM balancer, 24 sessions: 58.82 svLLM balancer, 32 sessions: 82.84 svLLM balanceraffinity on, 4 sessions: 2.84 saffinity on, 8 sessions: 5.03 saffinity on, 16 sessions: 24.88 saffinity on, 24 sessions: 38.34 saffinity on, 32 sessions: 38.92 saffinity on
Fig. 7Time to first byte at 4 to 32 concurrent sessions, median and p95, on a log scale so the sub-second steps read beside the minute-long ones. With affinity the median is far lower up to 16 sessions (0.38 against 2.05 s at 4) and higher at 24 and 32; the p95 is lower at every step, though at 16 the gap (24.9 against 26.2 s) is within the noise of one run per arm. Measured at the client, over the internet, to the first streamed token.
SessionsSessions/h off → onOutput tokens/min off → onTTFB p50 off → on (s)TTFB p95 off → on (s)Replicas busy off → onPrefix hits off → on (%)Stayed on replica (%)
4180 → 2405,886 → 6,7442.05 → 0.383.5 → 2.842.71 → 2.8356.2 → 86.4100
8300 → 3808,364 → 10,7522.33 → 0.486.32 → 5.033.74 → 3.7444.3 → 86.1100
16300 → 3609,558 → 12,2043.25 → 0.8526.24 → 24.883.91 → 3.6933.2 → 48.6100
24300 → 4209,048 → 11,1785.06 → 13.1458.82 → 38.343.91 → 432.8 → 37.989.1
32520 → 62014,760 → 16,63812.32 → 27.6682.84 → 38.924 → 431.6 → 31.667.3

Measured on our four-card box with a small model, affinity off first, then on, without restarting vLLM in between: the second arm started with a warm prefix cache, and both arms drew their prompts from the same seed. Each step lasts 3 minutes, so it completes only 9 to 31 sessions and one session more or less moves sessions an hour by 20; output tokens a minute is the steadier column. Your model, cards and workload will differ; the replica card on a model’s page shows the same counters for yours.

Up to 16 sessions, affinity is ahead at every step on throughput, prefix-cache hits and both time-to-first-byte columns: hits go from 56 to 86% at 4 sessions, the median time to first byte from 2.05 to 0.38 s, and output from 5,886 to 6,744 tokens a minute (sessions an hour from 180 to 240). At 24 and 32 sessions, the overload steps, every replica is saturated. Output is still higher (11,178 against 9,048 and 16,638 against 14,760 tokens a minute) and the slow tail is much shorter (p95 38 against 59 s, and 39 against 83 s), but the median time to first byte is worse with affinity: 13.1 against 5.1 s at 24 sessions, 27.7 against 12.3 s at 32. We have not isolated why, and lowering the spill threshold from 8 to 4 did not change it. The advantage is largest while there is headroom; a box that runs at its limit should measure both settings, and affinity can be switched off per model.

Replicas busy by concurrent sessionsAverage replicas with running requests, of four, affinity on against vLLM’s balancer: 4 sessions 2.71 off, 2.83 on; 8 sessions 3.74 off, 3.74 on; 16 sessions 3.91 off, 3.69 on; 24 sessions 3.91 off, 4 on; 32 sessions 4 off, 4 on.affinity onvLLM balancerReplicas busy01234replicas busy, of 448162432concurrent sessionsvLLM balancer, 4 sessions: 2.71vLLM balancer, 8 sessions: 3.74vLLM balancer, 16 sessions: 3.91vLLM balancer, 24 sessions: 3.91vLLM balancer, 32 sessions: 4vLLM balanceraffinity on, 4 sessions: 2.83affinity on, 8 sessions: 3.74affinity on, 16 sessions: 3.69affinity on, 24 sessions: 4affinity on, 32 sessions: 4affinity on
Fig. 8Replicas busy, of four: replicas with requests running at each poll, averaged over a step. Not GPU utilisation. Affinity barely changes it; the gain is in fig. 9.
Prefix-cache hit rate by concurrent sessionsShare of prompt tokens served from the prefix cache in each step, all four replicas pooled, affinity on against vLLM’s balancer: 4 sessions 56.2% off, 86.4% on; 8 sessions 44.3% off, 86.1% on; 16 sessions 33.2% off, 48.6% on; 24 sessions 32.8% off, 37.9% on; 32 sessions 31.6% off, 31.6% on.affinity onvLLM balancerPrefix-cache hit rate0255075100% of prompt tokens48162432concurrent sessionsvLLM balancer, 4 sessions: 56.2%vLLM balancer, 8 sessions: 44.3%vLLM balancer, 16 sessions: 33.2%vLLM balancer, 24 sessions: 32.8%vLLM balancer, 32 sessions: 31.6%vLLM balanceraffinity on, 4 sessions: 86.4%affinity on, 8 sessions: 86.1%affinity on, 16 sessions: 48.6%affinity on, 24 sessions: 37.9%affinity on, 32 sessions: 31.6%affinity on
Fig. 9Prefix-cache hit rate in each step: prompt tokens served from the cache over prompt tokens asked for, all four replicas pooled, from the change in vLLM’s own counters over the step. The gain holds while there is headroom and is gone at 32 sessions, where conversations spill.
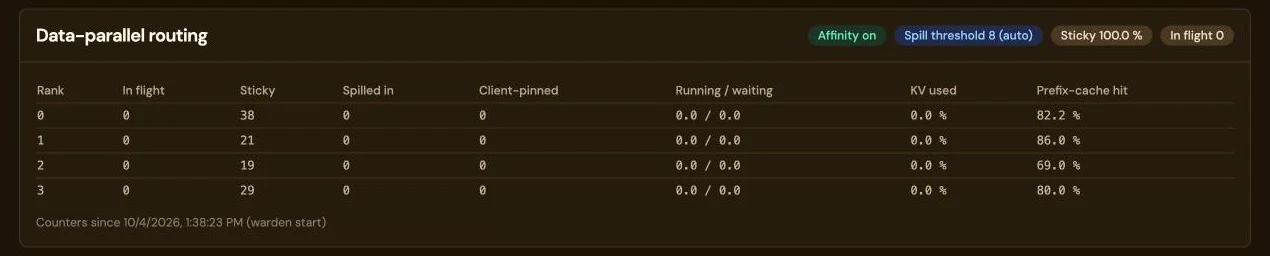
The Data-parallel routing card on a model’s page, with the pills Affinity on, Spill threshold 8 (auto), Sticky 100.0% and In flight 0. A table lists replicas 0 to 3 with in flight, sticky (38, 21, 19 and 29), spilled in, client-pinned, running and waiting, KV used and prefix-cache hit rate (82.2, 86.0, 69.0 and 80.0 percent), and a line saying the counters run since the warden started. Affinity on, spill threshold 8 (auto) Hit rate per replica, from vLLM’s own counters
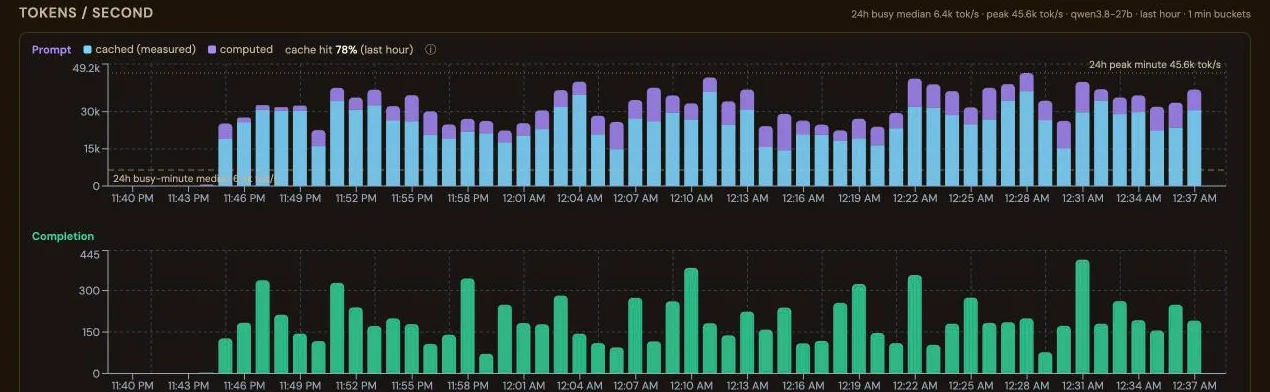
Fig. 10The same counters on a model’s page: one row per replica with the requests it holds, how many conversations stayed (sticky) or arrived by spilling, what is running and waiting, KV cache in use and the prefix-cache hit rate. Recorded on 4 October 2026 with affinity on and the spill threshold at 8 (auto): sticky 100%, 38, 21, 19 and 29 sticky requests on replicas 0 to 3, and a prefix-cache hit rate of 82.2, 86.0, 69.0 and 80.0%. The counters run since the warden restart, and all traffic in that window ran with affinity on: synthetic agent sessions plus real Claude Code turns. It is the card, not a result. Scroll the image sideways to see every column.

The box that first prompted replica routing has run with it since. It has seven RTX 5090s serving a 27B model as seven one-card replicas to a farm of headless Claude Code agents. Our first placement rule hashed the session id, which was sticky but blind to load. With 26 agent sessions of about 58k tokens each, three replicas sat idle while others ran their cache up to 93%, and the share of prompt tokens served from the cache fell from 81% after a restart to 28% within about 35 minutes. We then cut the farm to 16 sessions, about two per replica, so the working sets fit the cache, and placed new conversations on the least-loaded replica. Over the next hour it was 78 to 79%. That is an observation, not an A/B: one workload and two changes made together, so the gain is not placement’s alone. The rule of thumb it suggests: keep concurrent sessions times their typical context under the box’s total cache.

The Tokens per second chart from the Stats page over one hour. The prompt bars are split into cached, measured, in blue and computed in purple, between about 15k and 45k tokens a second, most of each bar blue, with the summary cache hit 78% over the last hour. Completion tokens per second, between about 70 and 420, are drawn in green below. Measured by the engine, per request
Fig. 11Prompt tokens a second on the seven-GPU box, split into what each replica read from its prefix cache and what it had to compute, with the share for the last hour: 78%. The cached part is the engine’s own count for each finished request, not an estimate; a request it did not measure counts as computed. Recorded on 5 October 2026. Scroll the image sideways to see the whole hour.